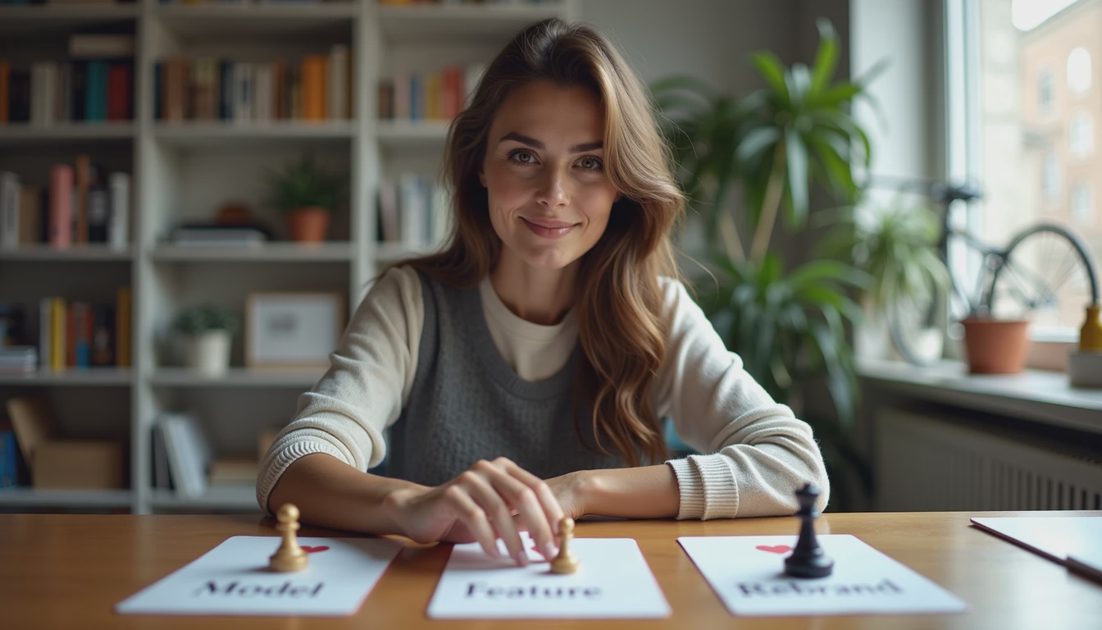
AI model comparison coverage often begins in the wrong place. It begins with a name. A lab publishes a new label, a score, and a paragraph about “next-generation capabilities,” and the internet treats the label as a new object. Sometimes it is. Sometimes it is a mid-cycle improvement, a pricing change, a routing layer, or a fresh coat of product paint on a model you have already used under another name.
I write this as a practical reader’s guide because AI product launch analysis should classify the event before it ranks the model. Classification is not glamorous. It prevents you from writing a revolution essay about a point release.
Three Labels That Get Collapsed Into One Headline
A model release changes the underlying system in a way you can test: weights, architecture, context window, tool use, or training mixture that shows up in behavior. A feature update changes what a product can do with a model you may already have: a new connector, a memory toggle, a voice mode, an admin log. A rebrand changes the name, the packaging, the SKU, or the landing page without a corresponding change in the thing you can measure.
Companies have reasons to collapse the three. A new name resets the news cycle. A feature can be demoed more easily than a training run. A rebrand can move a model from a research blog to a sales deck. Readers have a reason to keep them apart: your risk, your contract, and your evals depend on which one happened.
A field guide
If the API model string changed and behavior changed on a frozen prompt set, you are closer to a model release.
If the model string is stable and a new button appeared in the app, you are looking at a feature update.
If the landing page changed, the price tiers were renamed, and the evals are recycled, start with rebrand as your working hypothesis.
If the company will not say whether the new name maps to a new checkpoint, treat that refusal as part of the story.
Read the announcement. Then read the incentives.
How I Test the Claim Without a Lab
I do not run a foundation-model training cluster from a Brooklyn apartment. I do compare public artifacts. System cards, model cards, API changelogs, price sheets, rate limits, and independent leaderboards are all incomplete. Together they are better than a keynote.
AI model comparison that relies on a single vendor chart is just the chart with more adjectives. I look for whether the vendor published the evaluation protocol, whether independent arenas moved, and whether practitioners I trust—people who ship software, not people who quote press releases—report a change that survives a week of use.
What public artifacts can and cannot show
Artifact | Can show | Cannot show |
|---|---|---|
Changelog / model string | That something was deployed | Why behavior changed |
Vendor eval table | The tasks they chose to highlight | Tasks they did not run |
Independent arena or benchmark | Relative preference or accuracy on a set | Your production distribution |
Price and rate-limit sheet | Economic and capacity constraints | Quality |
System card | Intended uses and known limits as the vendor sees them | Undisclosed failure modes |
The table is a humility device. It keeps me from over-reading a 2-point bump on a benchmark that may not match any customer’s traffic.
Why Rebrands Happen on a Schedule
Naming is strategy. A research name signals caution and invites papers. A product name signals readiness and invites procurement. Moving a system from the first bucket to the second is sometimes earned and sometimes merely scheduled for a conference.
There is also routing. A product may call one name and send different queries to different models. From the user’s seat that can feel like a “smarter” release. From the engineer’s seat it can be a traffic policy. Both can be true. Only one belongs in a model comparison chart.
Questions I ask in the first hour
Is there a new model identifier a customer can pin?
Did context length, tool access, or multimodality change in the docs?
Did pricing per token, per seat, or per task change?
Are yesterday’s evals being reused with a new logo?
Can a customer refuse the change and stay on the prior checkpoint?
If the answer to the last question is no, then even a quiet update is an operational event. Forced migrations are product news whether or not the marketing team sent a note.
A Calm Way to Read the Next Name Drop
I still cook a long pasta sauce on nights when a major lab is presenting. It is a useful timer. If the only thing that has been confirmed by the time the sauce is done is a new name and a demo, I write it that way. If a pin-able checkpoint, a doc change, and an independent signal have arrived, I write that too.
Here is what changed, and what did not. The industry got faster at shipping incremental model improvements and faster at naming them as events. The reader’s job—separating weights, wrappers, and words—did not get easier. This is meaningful if you care about what you are actually calling. It is not yet a reason to reset your entire stack because a slide said “new.”
The signature I come back to is the same. Read the announcement. Then read the incentives. The incentive, often, is to make a feature or a rename travel as far as a model release. Your notes do not have to follow.
No notes on this sheet yet.